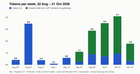
TL;DR: In 60 days I made ~1.3K commits across 17 personal repos using ~18B tokens, 70% of them on my ChatGPT Pro plan. What made it work: Claude acts as manager, GPT models work, a few guardrails keep agent-written code from turning to shit, and cleanup passes turn the sprawl back into something a human can read.
You don't NEED Claude for this; GPT-6 Astra could orchestrate too.
Some will be happy to point out this isn't the MOST efficient use, but those tokens were going to waste otherwise. This is a learning process for me.
Most importantly, THIS ISN'T SCRIPTURE. I would love to hear your take on this approach and learn some things myself.
The numbers
| What | Count |
|---|---|
| Commits | 1,255 across 17 repos, 65% co-authored by an agent |
| Tokens | 18.3B: 12.9B on OpenAI models, 5.5B on Claude (which I only had for the last 30 days) |
| Subagents | 711 spawned, 137 of them inside scripted workflows |
| Peak day | 1.9B: one Codex thread building my van dashboard with 13 sub-agents |
| Weekly cap | Hit 100% on 7 days, plus 4 banked resets burned |
Yes, most of those tokens are cached input. Don't @ me. Raw token counts are a shit meter anyway. The week I pushed 3.5B through Codex CLI (97% cached), my weekly limit peaked at 26%. In October I maxed it out again and again on 2–2.5B a week. The headline number tells little about how hard you're hitting the plan.

Trust the meter, not your token math. I got my own numbers wrong twice writing this. Forked Codex sub-agents copy the parent's running token total, so summing session logs counted 3.4B tokens that never happened. And Claude Code only saved final usage for ~a third of its GPT-worker requests and logged the rest as uncached, so they looked like they missed cache 77% of the time (actual: ~4%). Codex logs its own limit percentages; read those.
The setup
Claude Code runs my show. Model-gateway plugin (Eigenwise's) lets Claude Code use GPT models via ChatGPT login, so the subagents it spawns run on the OpenAI plan. There are three worker tiers:
- GPT-6 Astra: hard bugs, judgment calls, a second opinion from another model family
- GPT-5.6 Sol: well-specced work that still needs real reasoning
- GPT-5.6 Luna: mechanical edits
Why GPT does the volume: my Codex allowance was 2–4x my Claude plan's, I got a pile of resets on top, and I only added Claude a month in. So Claude plans, delegates, reviews and commits, the OpenAI plan eats the tokens. ~5B tokens went through that route, and Codex CLI used another ~8B directly.
Global rules I recommend
- Never let workers inherit the boss's model. Pin every subagent to a model. Otherwise each one quietly runs on your most expensive model, and you're left wondering where your week went.
- Workers report once. Tell every worker to shut up until it's done, then report. Each mid-run message wakes the parent and burns a full turn.
- Handoff notes. One
.agent/handoffs/<workstream>.mdper workstream: goal, decisions, done, next. Claude and Codex both read it, so either picks up where the other stopped. Delete it when the work ships. - Size ratchet. Agents add features one reasonable edit at a time until you're staring at a 3,000-line god file wondering who the hell wrote it. You did, by robot. A Stop hook checks file and function sizes against a committed baseline, and any change that makes them worse fails the turn. The baseline only moves in a deliberate rebaseline commit. In my biggest repo, 80+ line Python functions went 85 → 47 and oversized files 24 → 13 while the code grew 29%.
- Refactor with receipts. Audit → ranked tickets → one worktree per ticket. GPT implements, Claude reviews, old vs new output gets compared before anything merges. One split kept 64 functions byte-identical across 56 scenarios; another replayed 882 guarded command paths. "Looks right" is not a test.
- Shorthand commands.
+sa(use subagents),+ir(investigate, fix the root cause, verify),+rcp(review uncommitted work, commit, push),+le(list loose ends),+art(turn the chat into a summary page). Defined once in the global instructions, mirrored for Claude and Codex. - Only get pinged when blocked. Phone notifications fire on permission prompts and questions, never on "turn finished". Otherwise you're checking your phone like a slot machine. It's what makes 10+ parallel sessions bearable.
- Boring shit that pays off:
- restore every open session after a reboot
- map each uncommitted file to the session that wrote it, so parallel agents don't commit each other's half-finished work
- search every transcript across both tools
- compress shell output before it hits context

Making agent-built code readable again
Agents don't organize. They drop autofill_rules.ts next to autofill_store.ts next to 160 other files in one folder, and keep growing whatever file the last feature landed in. It all works, and no human can find shit in it. So a chunk of the burn went to reorganizing, with the same receipts as any refactor:
- Flat folders → feature folders. My job-search app's server folder had 169 files at one level. This week's pass moved the Gmail, autofill, careers, Claude-session and job-pull code into their own folders; 114 left for the next pass.
- God files → named pieces:
- video library: 3,469 + 3,037 lines → 13 modules
- system monitor: 3,215 lines → 9 modules
- Wi-Fi manager: 1,551 lines → 193-line dispatcher + 8 modules
- display dimmer: 621 lines → 142-line entry point + model, adapters, runtime
- Hacks out. Van telemetry repo: 64
sys.pathhacks → 0 once it became a real package. - Nothing breaks on the way. Old vs new output compared, live services rechecked, and anything systemd or launchd calls keeps its path or gets a shim.
Layout rules for backend code
These keep it from sliding back. The ratchet stops bloat; these decide where shit goes (services, CLIs, workers and script folders in Python, Node, shell and Go):
- Thin entry points. Parse args, build a config record, call one function.
- Decisions stay pure: no clock, sockets, files or subprocesses. One adapter per external thing, named after it. No
utils/,helpers/orcommon/; those are junk drawers with a nicer name. - 3+ files sharing a prefix (
radar_*,autofill-*) are a candidate feature folder:radar_alignment.py→radar/alignment.py. Check they actually belong together first. - Contracts table in AGENTS.md lists every path something outside the repo calls (systemd, launchd, cron, npm scripts). A checker verifies it against the real unit files.
- Moving a contract path leaves a shim naming its owner, its callers and when it can die.
- Split god modules in this order: pure decisions out, then adapters, then the main loop into named phases. Never
part2.py, never a_helpers.pydumping ground. - The checker ratchets too. Existing mess is baselined and reported; only new violations fail.
What all that built
- Job-search workbench: finds roles, scores fit, generates tailored resume and cover letter PDFs, and prefills applications without ever auto-submitting. Also watches Gmail for replies.
- Van telemetry: I live in a campervan. Reverse-engineered its CAN bus (speed limit, adaptive cruise state, oil life, compass and more) and built a live tablet dashboard with early warnings and tire-pressure trends.
- Van dashboard: one screen for backups, network, media, lights and compute. My favorite might be remote door lock/unlock via local net or Starlink uplink.
- Compute broker: the Raspberry Pi hands heavy jobs to my M4 Mac, which runs them in no-network sandboxes.
- Session switchboard: web console for every Claude and Codex session on both machines; keeps the important ones alive for remote control. 52 commits in 8 days.
- Electronics inventory: photograph a part, AI drafts the record, search it all offline.
- Critter generator: invents creatures with portraits, field notes and a 3D-printable STL.
- Backup safety: transactional backups with locks, fences and rollback.
- Site + self-hosting edge: hand-tuned design system / OKLCH palette. Behind it, a small Hetzner box where one
edge.jsonregistry generates the Cloudflare Tunnel routes and DNS for every app I stand up. Each app gets its own access policy and listens only on loopback. The deploy refuses to ship anything outside the build output or anything private. My personal demo site: lionfeather.dev - Also: a health journal with trend charts, a YouTube cast receiver on the Pi, media tools and a fat pile of Mac automation shit.
Van telemetry, replaying a past drive.


Got a week of 20x left? Consider this
- Write your rules into AGENTS.md and CLAUDE.md now. Whatever cheaper model you end up with inherits the discipline.
- Point your best model at your messiest repo: audit, tickets, refactor with old vs new output checks. Flat folders → feature folders, god files → named pieces.
- Install a size ratchet so nothing you build this week rots into another shitpile monolith next month.
- Have agents write a README with screenshots for every project. You will forget what half this shit does.
- Build the boring tooling: session restore, transcript search, "which session wrote this file".
Happy to share the actual rule files or prompts if anyone wants them.
Source: r/codex · by /u/Legitimate-Act5864