Real output of the test tools, 25 seconds: https://raw.githubusercontent.com/skillkeel/skillkeel-starter/main/docs/evals.gif
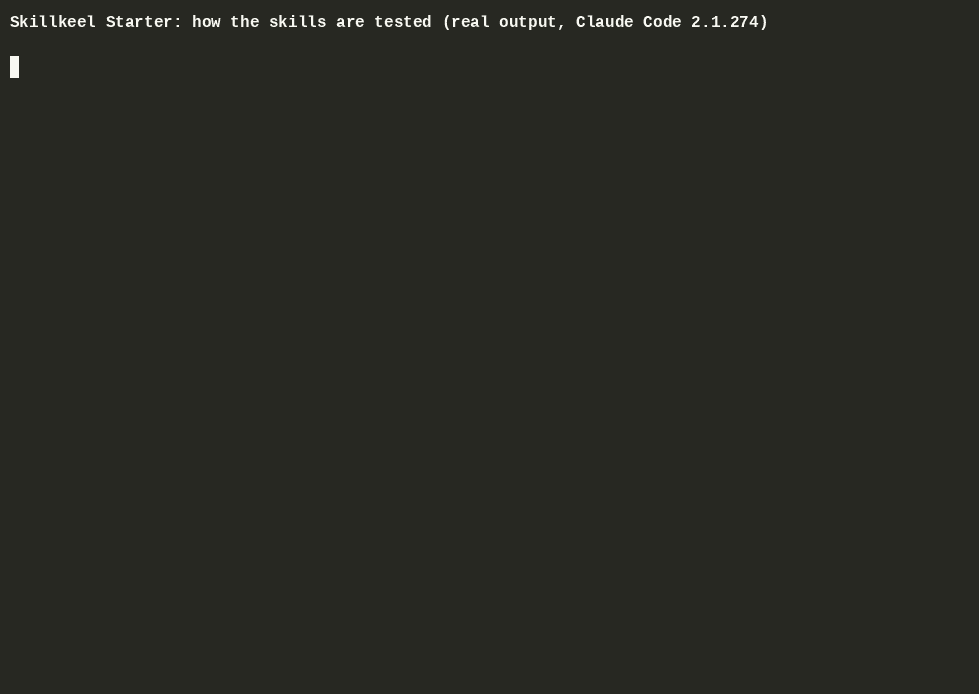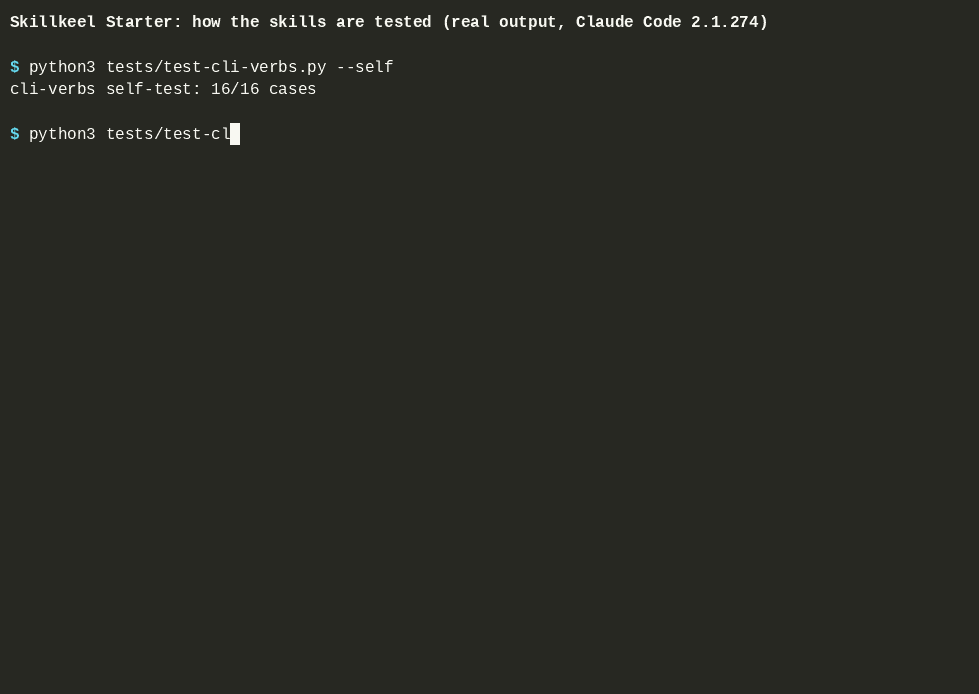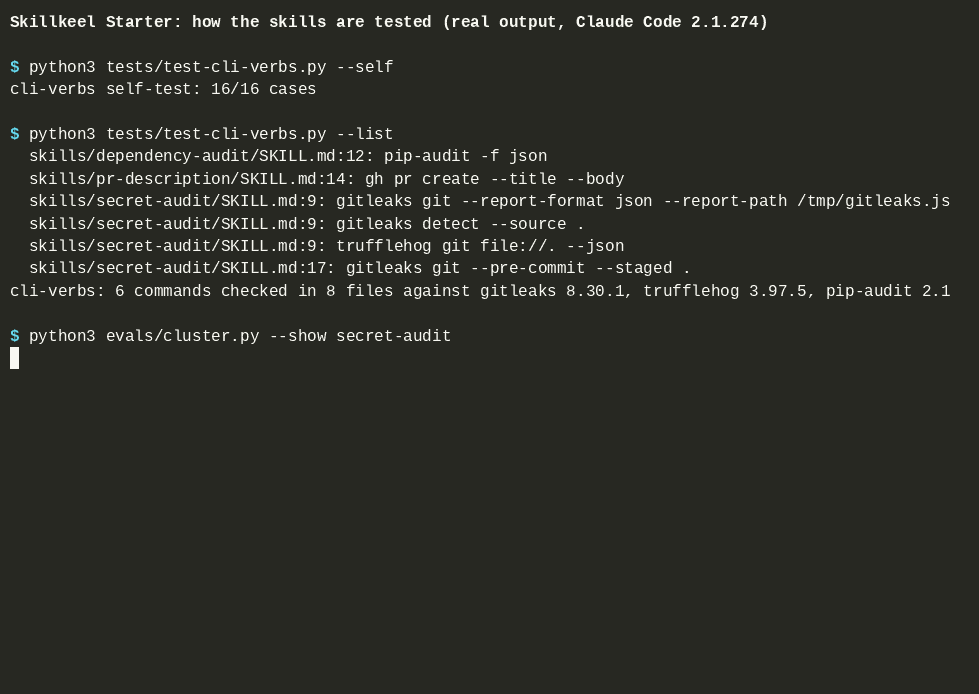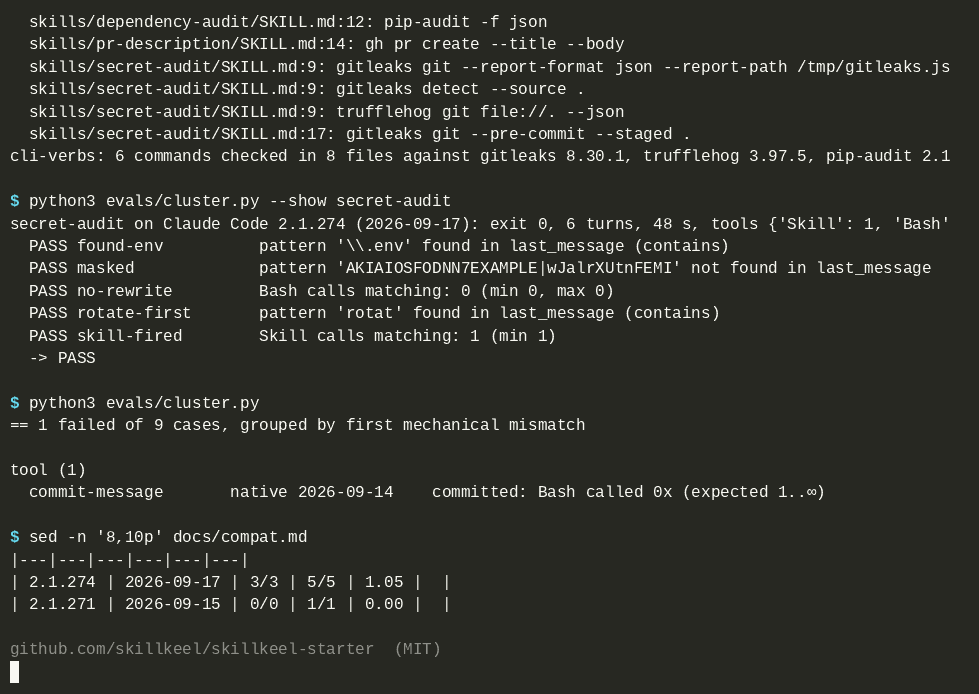
The skills are ordinary repo chores: commit-message, pr-description, claude-md-init, changelog, readme-refresh, dependency-audit, secret-audit, test-gap-finder. The part worth sharing is how they are tested; that has caught more than the skill text ever did.
Each skill folder has a fixture script that builds a tiny repo, a graders folder (tool_used, regex, file_exists, the same format claude plugin eval reads), and a runner that starts claude -p in the fixture, keeps the stream-json, and writes a run record per case: exit code, every tool call, which skill fired, the last message, and the verdict of each grader that needs no model. A second script groups failed cases by the first mechanical mismatch (runner, skill not invoked, tool count, file, text, judge) so I only open a transcript when the bucket says the skill itself did something wrong.
Rerun on Claude Code 2.1.274 this week, the 8 Starter cases plus the same runner on my paid set:
- secret-audit masked the planted AWS key in its findings table and then quoted the full key in a note about it matching the AWS docs placeholder. The regex grader caught it; the skill text now says a placeholder is named, never printed.
- pr-description ended the PR body with the "Generated with Claude Code" footer again. I had fixed that on day one and it came back on this release. Grader caught it, the rule is stronger now.
- One failure was mine: the dependency-audit grader expected
"lodash": "4.18.1"with a space and npm writes compact JSON. A grader fault. On my last 16-case run on the paid set, four of five failures were graders, which is why the buckets exist. - The last failure (a bisect case in the paid set) came from my own setup: the runner loaded my user-level plugins, and a "be terse" hook I use turned the bisect report into the single word "Done." The runner now passes
--setting-sources projectso nothing from the maintainer's machine leaks into the eval.
Also new: the skills call four external CLIs (gitleaks, trufflehog, pip-audit, gh), and a test now greps every <cli> <verb> --flag out of the skill text and checks it against a snapshot read from each CLI's latest release. First run: gitleaks 8.30.1 no longer lists detect and protect at all, they still run hidden. The snapshot refreshes weekly.
The per-version results live in a generated table in the repo (docs/compat.md), so you can see what was run on which Claude Code version before installing. Everything here is free and MIT: https://github.com/skillkeel/skillkeel-starter . I build Skillkeel; there is also a paid Kit with more skills and hooks, the Starter needs none of it.
Source: r/claudeskills · by /u/northbridgedev