
Hey guys,
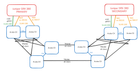
I know this isn't a proper solution, and unfortunately, I cannot change the design. I have two Juniper SRX 380s that are geographically separated. They have a L2 between them.
Given the model is an SRX 380, I cannot do NMHA as its not supported. I am trying to make both Junipers on a Chassis Cluster
I already have Juniper PRIMARY set with all the config and fab interfaces and everything working. and I was trying to joing the secondary node to the cluster.
Note I have spanned all vlans (vlan200 = Control Link) and (vlan100 = Fabric Interfaces)
Strangely enough, when I joined the Secondary node to the cluster, after a while, it in fact was able to talk with the primary node, and was able to gather the config and such. It worked, so I thought.
After a minute or so, it went down back to hold. I've checked logs, checked statistics, I am not having any luck. Does anybody knows why this happened?
{primary:node0} admin@SRX-PRIMARY> show configuration ## Last commit: 2026-08-25 07:47:44 UTC by admin version 21.2R3-S2.9; groups { node0 { system { host-name SRX-PRIMARY; services { ssh { root-login allow; protocol-version v2; } } } interfaces { fxp0 { unit 0 { family inet { address 10.210.8.1/29; } } } } } node1 { system { host-name SRX-SECONDARY; services { ssh { root-login allow; protocol-version v2; } } } interfaces { fxp0 { unit 0 { family inet { address 10.210.8.5/29; } } } } } } apply-groups "${node}"; chassis { cluster { control-link-recovery; reth-count 2; redundancy-group 0 { node 0 priority 250; node 1 priority 150; } redundancy-group 1 { node 0 priority 200; node 1 priority 100; } } } {TRIMMED} interfaces { ge-0/0/15 { gigether-options { redundant-parent reth1; } } xe-0/0/18 { gigether-options { redundant-parent reth0; } } xe-0/0/19 { gigether-options { redundant-parent reth0; } } xe-5/0/18 { gigether-options { redundant-parent reth0; } } fab0 { fabric-options { member-interfaces { xe-0/0/16; xe-0/0/17; } } } fab1 { fabric-options { member-interfaces { xe-5/0/16; xe-5/0/17; } } } lo0 { unit 0 { family inet { filter { input PROTECT_RE; } address 192.168.101.1/32; } } } reth0 { vlan-tagging; redundant-ether-options { redundancy-group 1; lacp { active; } } reth1 { redundant-ether-options { redundancy-group 1; } unit 0 { description "Temp Internet Link"; family inet { address REDACTED-PUBLIC-IP; } } } } firewall { family inet { filter PROTECT_RE { term SYNFLOOD_PROTECT { from { protocol tcp; tcp-flags "(syn & !ack) | (rst) | (fin)"; } then { policer PLCR-RE-TCP-FLAGS; accept; } } term DENY_ICMP_FRAGS { from { is-fragment; protocol icmp; } then { count PROTECT_RE_DENY_ICMP_FRAGS; log; discard; } } term ALLOW_ICMP { from { protocol icmp; } then { policer POLICE_1M; count PROTECT_RE_ALLOW_ICMP; accept; } } term ALLOW_TRACEROUTE { from { protocol udp; destination-port 33434-33523; } then { policer POLICE_1M; count PROTECT_RE_ALLOW_TRACEROUTE; accept; } } term ALLOW_SSH { from { source-prefix-list { WORKSTATIONS; } protocol tcp; destination-port ssh; } then { count PROTECT_RE_ALLOW_SSH; log; syslog; accept; } } term ALLOW_DNS { from { protocol [ tcp udp ]; destination-port 53; } then { count PROTECT_RE_ALLOW_DNS; accept; } } inactive: term ALLOW_SNMP { from { source-prefix-list { SNMP-SERVER; } protocol udp; destination-port snmp; } then { policer POLICE_10M; count PROTECT_RE_ALLOW_SNMP; accept; } } term ALLOW_RADIUS { from { source-prefix-list { RADIUS-SERVER; } protocol udp; source-port radius; } then { count PROTECT_RE_ALLOW_RADIUS; accept; } } term ALLOW_OSPF { from { source-prefix-list { WORKSTATIONS; } protocol ospf; } } term TCP_ESTABLISHED { from { protocol tcp; tcp-established; } then { policer POLICE_10M; count PROTECT_RE_TCP_ESTABLISHED; syslog; accept; } } term DEFAULT_DENY { then { count PROTECT_RE_DEFAULT_DENY; log; syslog; discard; } } } } policer PLCR-RE-TCP-FLAGS { if-exceeding { bandwidth-limit 1m; burst-size-limit 62500; } then discard; } policer POLICE_100K { if-exceeding { bandwidth-limit 100k; burst-size-limit 15k; } then discard; } policer POLICE_10M { if-exceeding { bandwidth-limit 10m; burst-size-limit 625k; } then discard; } policer POLICE_1M { if-exceeding { bandwidth-limit 1m; burst-size-limit 15k; } then discard; } } {TRIMMED} {primary:node0} admin@SRX-PRIMARY> Looking through the logs, it appears the HA/chassis cluster is having serious communication issues between the two nodes.
The control link is repeatedly dropping and reconnecting, while the fabric link never successfully comes up. The fabric interfaces themselves appear physically up, but the forwarding plane sees them as down, so the cluster can't establish stable node-to-node communication.
There are also signs that one of the fabric-facing FPC/PICs (on Node1) may have restarted or become unstable, as interfaces are repeatedly being deleted and re-added around the same time the cluster issues occur.
Has anyone seen similar behavior where the control link keeps flapping and the fabric interfaces are physically up but remain down from the cluster's perspective?
* If I restart the SRX-SECONDARY, it will temporarily join the cluster and then disconnect back again and will never become 'online' until I manually reboot it.
NOTE: I have set MTU to 9192 throughout the entire L2 Path.
Thanks guys!
Source: r/Juniper · by /u/Qvosniak