Everyone here talks about getting cited. We wanted to answer something more basic first: when an AI answers a buyer question, how often does it show its sources at all?
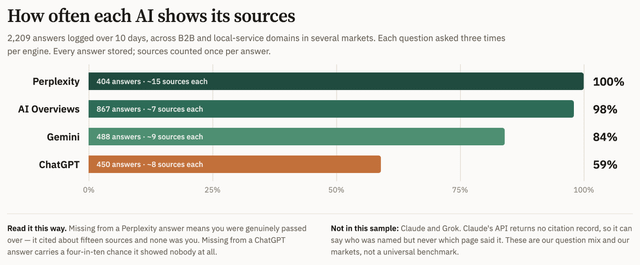
So we counted. 2,209 answers over 10 days, across B2B and local-service domains in a few different markets. Every answer stored, sources counted once per answer.
The one that surprised us was ChatGPT at 59%. There is a figure going around that "87% of ChatGPT responses cite sources". Ours came in a lot lower. I am not saying theirs is wrong, different question mix, different markets, different month. But if you are planning around 87%, worth checking on your own prompts before you do.
Why this changes how you read a gap
Absence is not one thing.
Missing from a Perplexity answer means you were genuinely passed over. It cited fifteen sources and none of them was you. That is a real finding and you should act on it.
Missing from a ChatGPT answer carries a four-in-ten chance the engine showed nobody at all. You have learned almost nothing about yourself.
Any tool that averages those two into one "citation rate" is mixing a real loss with a non-event. We stopped trusting our own number until we split it by engine.
The second thing, which changed how we pick prompts at all
A lot of buyer questions cannot be won by anyone. You ask "how do I improve X" and the answer is advice, no brands named. There is no shortlist to get onto, so tracking that prompt forever proves nothing except that you are paying for it.
We now run every candidate question against an engine before it enters a tracked set, and drop it if the answer names fewer than 2 brands (advice, not a shortlist) or more than about 14 (a directory, not a recommendation). On a typical run about 60 questions get tested and 5 survive. We keep the rejected ones with the reason attached, because "we dropped this and here is why" is more useful than a longer list.
Method, so you can pull it apart
- Each question asked 3 times per engine, not once. Two runs of the same prompt return the same brand list less than 1 in 100 times, so a single pull is not a measurement.
- Anything named in exactly 1 of 3 runs goes back out for 9 more runs before it counts. Otherwise you are reporting a coin flip.
- Counted once per answer, never per mention. A brand named four times in one answer counts once, or a talkative model looks like market share.
- No Claude or Grok in this sample. Claude's API returns no citation record, so it can tell you who was named but never which page said it.
What I would still call unproven: we have not split this by question type yet. My guess is comparison-intent questions ("X vs Y", "best tool for Z") cite more than definitional ones, and that would move ChatGPT's number. Have not measured it, so I am not claiming it.
If you have measured this on your own prompt set I would genuinely like to compare, especially if your ChatGPT number is nowhere near 59%. That is the one I am least confident in.
Disclosure: we build an AI-visibility tool, so I am not a neutral party. No link, and I am happy to keep it that way. I am posting because I could not find anyone publishing their own measured numbers instead of quoting each other's. Ask me anything about the method.
https://i.redd.it/e04qzqtojaph1.png
Source: r/aeo · by /u/Narrow_Hall_7273